

AMD Instinct™ MI350P PCIe now available in the MEGWARE Benchmark Center
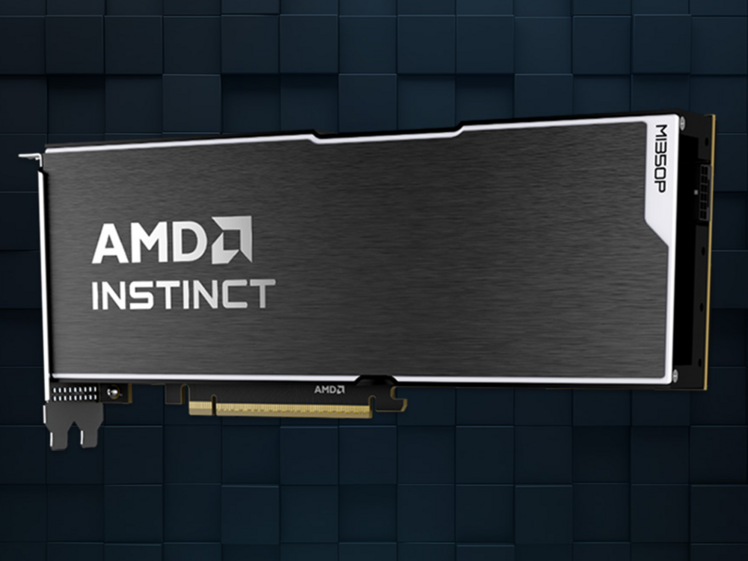
The MEGWARE Benchmark Center has been extended with AMD's latest CDNA™ 4 accelerator: the AMD Instinct™ MI350P PCIe card is available now for customer test workloads.
144 GB of HBM3E in a standard PCIe form factor
With 144 GB of HBM3E per card, the MI350P lets you run models on a single GPU that previously required two or four accelerators. Because it is a standard dual-slot PCIe 5.0 add-in card, it drops into existing server platforms - no OAM baseboard, no new rack design. That makes it an interesting option for customers who want to run generative and agentic AI inside an installed base rather than build a new island.
Key specifications
| Architecture | AMD CDNA™ 4 (TSMC 3nm), 128 CUs, 512 Matrix Cores | |
| Memory | 144 GB HBM3E, 4 TB/s, 128 MB LLC, full-chip ECC | |
| Form Factor | PCIe 5.0 x16, dual-slot, full height, 267 mm, passive cooling | |
| Power | 600 W TBP, configurable down to 450 W | |
| Peak performance | 4.6 PFLOPS MXFP4/MXFP6, 2.3 PFLOPS FP8/INT8, 1.15 PFLOPS FP16/BF16, 36 TFLOPS FP64 | |
| Virtualization | SR-IOV, RAS support |
New in CDNA 4 is native MXFP4 and MXFP6 support - a genuine step up over MI300X for quantized inference, and the reason very large MoE models now fit into a single card.
What you can run on it
As a rule of thumb, 144 GB of HBM leaves room for roughly:
- 60B parameters at BF16
- 120B at FP8
- 240B at FP4
including KV cache and activations.
Examples that run on a single MI350P under ROCm:
- Mistral Small 4
- 119B total, 6.5B active
- ~119 GB at FP8
- Low-rank MLA keeps the KV cache small
- European weights
- Qwen3.5 122B-A3B and Nemotron 3 Super 120B-A12B
- ~120 GB at FP8
- ~60 GB at FP4
- Qwen3.8-Flash-Next
- ~180B total, 6B active
- ~93 GB at FP4
- 262K context
- gpt-oss-120b
- 65 GB in MXFP4
- Apache 2.0.
- Native MXFP4 weights map directly onto CDNA 4's FP4 path
- Qwen3-Coder-Next 80B-A3B
- ~80 GB at FP8
- coding and agent workloads
- FLUX.1-dev, SDXL and Whisper large-v3
- image generation and ASR
- LoRA- and QLoRA-Finetuning
- of 70B-class models
Larger frontier models such as DeepSeek-R1/V3 (671B) scale across multiple cards.
Software-Stack
ROCm™ 7 with vLLM, SGLang, llama.cpp, PyTorch, JAX, Triton, ONNX Runtime and TensorFlow. Pre-built containers are available via AMD Infinity Hub and the AMD Enterprise AI Reference Stack, so most existing CUDA-based pipelines port with minimal effort via HIP.
Test it now!
Benchmarking your own models and applications in the MEGWARE Benchmark Center is free of charge for an initial analysis. Our HPC and AI engineers support you with setup, tuning and interpretation of the results - and advise on the right configuration for production.
More information about AMD InstinctTM MI350P